
Vector Search Isn't Enough: Hybrid Search and Reranking for Enterprise AI
Learn why enterprise AI search needs keyword matching, vector retrieval, filters and reranking to find the right source documents and versions.
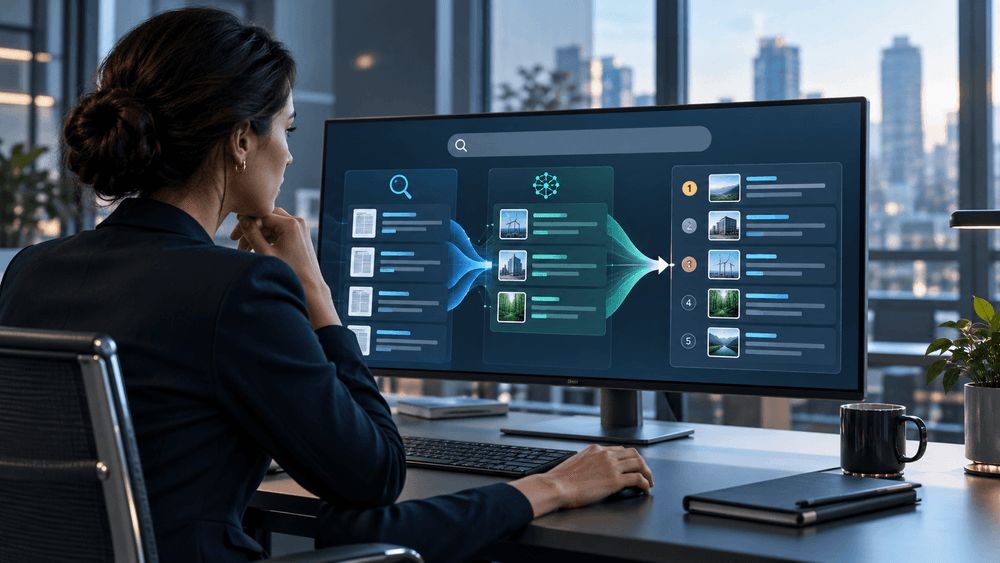
An employee asks an AI assistant for the procedure that governs an exception on a particular project. The system returns a document that sounds relevant, but it is for a different project and the wrong procedure version. The answer may be fluent, yet it cannot be trusted. This is one reason enterprise AI search needs more than a vector database and a language model.
Vector search is useful because it finds passages with similar meaning even when the wording differs. Business questions also contain exact terms that matter: a contract number, a product code, a customer name or a version date. Hybrid search combines semantic similarity with keyword matching, while filters and reranking help put the most useful authorised evidence first.
Where Vector Search Helps—and Where It Can Miss
Vector search turns text into numerical representations called embeddings. A question about “water ingress in a basement” can retrieve a report about “below-grade moisture intrusion” even when the words do not match. This is valuable in a company where different teams use different terminology for the same problem.
The same flexibility can be a weakness for exact identifiers. A query for procedure SOP-042 should not prefer SOP-024 because their surrounding text is similar. A request for a named customer or the latest revision needs precise matching and, often, a date or status filter. Similar meaning does not establish that a result applies to the specific case.
Keyword search is strong at exact words, phrases and identifiers. It is weaker when the user does not know the vocabulary used in the file. Rather than choosing one method for every query, an enterprise search system can use both. Azure AI Search's hybrid search documentation describes this combination of full-text and vector retrieval, including cases where product codes and names benefit from keyword precision.
How Hybrid Search Works in Practice
A hybrid query runs a text search and a vector search over the same body of information. It then combines the ranked results into one list. A passage might appear because it contains the exact contract number, because its meaning matches the question, or because both signals agree. The application can show the user the source document and the passage that supports an answer.
Suppose an operations manager asks, “What did we do when shipment AB-314 was delayed by a missing document?” The identifier should bring back that shipment's records. Semantic retrieval may also find a procedure for handling missing documents and a previous incident with a similar cause. The assistant can explain the relevant procedure and past precedent, but it must keep those sources distinct: a historical incident is not automatically the current rule.
Hybrid search does not remove the need to define which sources are authoritative. If a current SOP and an archived draft both rank highly, the system should prefer the approved version or state clearly that the records conflict. Ranking is part of the answer's reliability, not just a technical performance detail.
Filters Narrow the Evidence Before It Reaches the Model
Metadata filters can limit results to a customer, project, document status, language or date range. They also carry access restrictions. An employee who cannot open a commercial contract should not receive a passage from it through an AI answer.
These checks need to happen during retrieval, before the model receives the text. Filtering a generated answer afterward is too late if restricted content has already been supplied to the model. We explain the security design in more detail in our guide to permission-aware RAG.
Metadata must be maintained as sources change. A status field that never updates can make an obsolete procedure look current. An access list copied once at indexing time can become wrong when a project team changes. A production search system needs a refresh and revocation process as well as good ranking.
What Reranking Adds
Initial keyword and vector searches are designed to find a set of plausible candidates. A reranker then reviews those candidates more closely against the whole question and changes their order. This can promote a passage that directly answers the user's question over one that merely shares several terms.
Reranking is especially useful when a repository contains many near-duplicate documents or long procedures with similar headings. It is an extra computation step, so it can add latency and cost. The right question is whether it improves the answers employees care about enough to justify that work. Microsoft's semantic ranking overview explains how a second ranking stage can rescore initial search results.
A reranker cannot repair a missing or unreadable source. If a scanned PDF was indexed without usable text, if the current file was never ingested or if access rules excluded the correct record, the candidate set is already wrong. Document preparation and source governance matter as much as the ranking model.
Test Search With Real Company Questions
A useful evaluation set should include exact identifiers, synonyms, ambiguous project names, old versions and questions whose answer is absent. For each question, identify the source passage a knowledgeable employee would expect to see. Then compare keyword-only, vector-only and hybrid retrieval, with and without reranking.
Look beyond whether the top result seems plausible. Did the correct passage appear in the first few results? Was the latest authorised version preferred? Did the system keep a past example separate from a current policy? Did it correctly return no answer when the evidence was missing? These checks reveal whether a search improvement helps daily work.
An enterprise RAG architecture connects ingestion, access control, retrieval and answer generation. Hybrid search and reranking improve one important part of that chain. Codativity can help test these choices on your own documents and questions, then build the retrieval approach that produces verifiable answers rather than impressive demonstrations.
25/10/2026
Contact Us
701, Opal Tower Business Bay, Dubai United Arab Emirates
P.O.Box 126732
Let's Work Together
© 2016 - 2026 Codativity Software Solutions. All Rights Reserved.