
Why Software Deployments Become Slow and Risky as Teams Grow
Find the handoffs, manual steps and recovery gaps that make software releases slow or risky, then choose a practical first improvement.
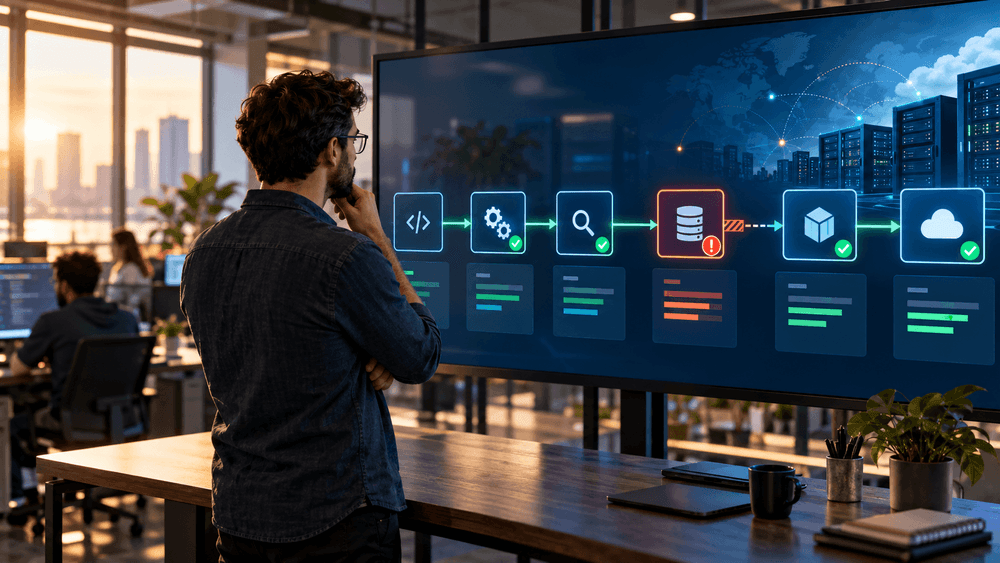
A small code change is ready on Tuesday, but it cannot reach users until the person who knows the server is available on Friday. The team has written tests, yet the release still depends on a checklist in someone's notes and a manual file transfer. When something goes wrong, nobody is certain which version was deployed.
That is a deployment process problem. It can affect an established product as easily as a new one. Before buying another tool, map how a change moves from a developer's computer to production, who approves it, and how the team recovers if it fails.
Map the Full Path From Code to User
Start with a recent release, not an idealized diagram. Record when the change was merged, built, tested, approved, deployed and checked in production. Note every handoff, waiting period and manual command. If several applications share a release window, identify which dependency forces them to move together.
The map often reveals a different bottleneck from the one people expected. A slow build may be visible, but the larger delay could be an unavailable test environment or unclear approval owner. A deployment script may work reliably for one engineer but lack the checks and documentation another engineer needs.
The DORA delivery metrics can help establish a baseline for change throughput and stability. Use them to understand your own service over time. A deployment frequency target alone can encourage the wrong behavior if failed changes or recovery time get worse.
Look for Manual Steps That Carry Production Risk
Some manual decisions are appropriate, especially when a change affects customer data or a regulated process. The risk lies in repetitive actions that must be performed from memory: copying files, changing configuration directly on a server, rebuilding an image after it passed testing, or running database commands without a rehearsed recovery plan.
Consider a web application with a staging environment. The team tests one container image, then rebuilds the same commit for production. If dependencies or base images have changed, production receives a different artifact. A more reliable process builds once, records the version, tests it, and promotes that same artifact through environments. Our CI/CD pipeline checklist explains the stages.
Shared administrator credentials and undocumented server changes create another problem. They make it difficult to know who changed an environment and whether the next deployment will reproduce the same configuration. Recording infrastructure and application configuration as code can reduce that drift, provided access and review are set up correctly.
Separate Release Speed From Release Safety
Teams sometimes keep releases infrequent because each one is stressful. Large batches then accumulate, making it harder to identify the change that caused a failure. Smaller, well-tested changes can be easier to inspect and recover, but only if the deployment process is repeatable.
A release should include a health check after deployment and an explicit decision about what happens if it fails. A successful pipeline job does not prove that users can sign in, complete an order or reach an API. Choose a few checks that represent the service's important paths, and make sure someone is watching them during and after the rollout.
Rollback also needs more than an old package. If a release changes the database schema or data, the previous application version may no longer work. Plan backward-compatible changes and test the recovery path before a bad release makes the decision urgent. Our article on deployments without downtime and safe rollback covers that problem in detail.
Make a Small, Measurable Improvement
Pick one application and one recent source of friction. A useful first step might be replacing a manual build with an automated one, creating a staging environment that resembles production, or documenting a rollback that another team member can execute. Measure whether the change shortens waiting time or reduces failed releases without adding a new approval maze.
Questions to ask during a release review
Can the team identify the exact code and configuration running in production? Does the same artifact pass through test and production, or is it rebuilt? Which steps require a particular person's account or memory? How is the release verified from a user's perspective, and who decides whether to roll back? Answers to these questions often reveal a more useful first project than a broad “DevOps transformation” initiative.
Keep a short record of releases and incidents so the next review uses evidence rather than recollection. If a deployment took two hours, separate active work from waiting for an approval, environment or missing credential. That distinction helps the team improve the constraint it can actually change.
The process will evolve as the product grows. A small team may need a simple pipeline and clear ownership; a larger platform may need a private registry and a GitOps deployment path. The right starting point is the release you actually run today. Codativity can review that path with your team and design the next improvement around its real bottleneck.
30/10/2026
Contact Us
701, Opal Tower Business Bay, Dubai United Arab Emirates
P.O.Box 126732
Let's Work Together
© 2016 - 2026 Codativity Software Solutions. All Rights Reserved.