
What Is Private AI? A Practical Guide for Businesses
Understand what private AI means, compare managed, hybrid and self-hosted options, and learn which data and access questions businesses should ask.
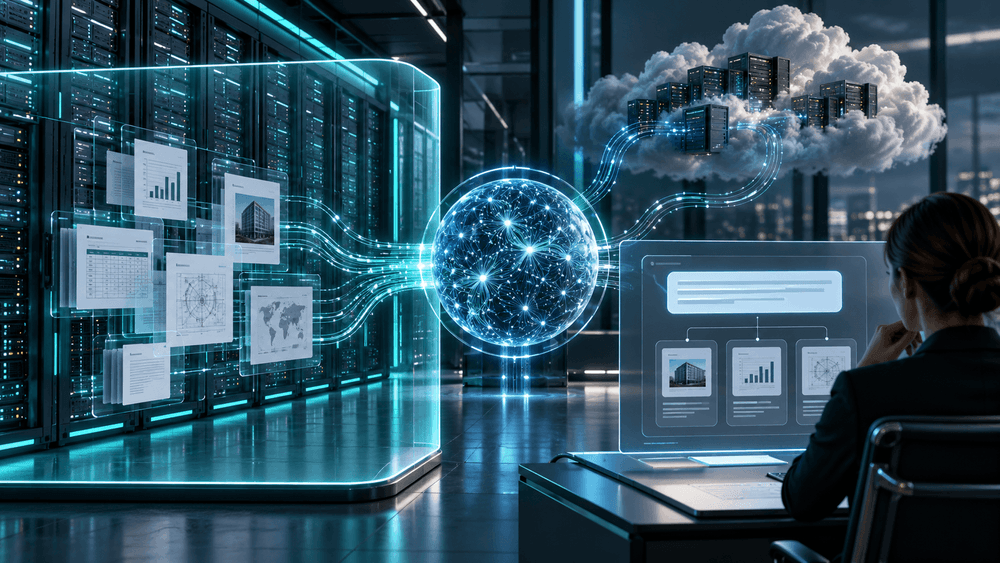
Many businesses want employees to use AI with internal information, but they are unsure where that information will go. A team may want to search contracts, technical files or customer records while keeping control of access, storage and model use. This is often described as “private AI,” although the term can mean different things to different providers.
The most useful way to evaluate private AI is to look past the label. Ask where company data is stored, which systems process it, who can access it and what happens to it after a request. Different architectures can meet different needs, and each still requires good security and governance practices.
What Does Private AI Mean?
Private AI is an approach to using AI in which an organisation defines and controls how its data is accessed, processed and retained. It commonly involves identity controls, restricted knowledge sources, contractual protections, logging and clear rules for the model and infrastructure that handle requests.
It does not always mean that every component runs on a server inside the company. Some businesses use a managed AI service with strict data terms and a private connection to their own information. Others keep the knowledge infrastructure in their own environment while using an external model. Some operate the full system on premises or in a dedicated cloud environment.
These options have different costs, maintenance needs and data paths. “Private” should be a description of specific controls, not a promise that any deployment is automatically safe.
Why Companies Ask for Private AI
The concern often starts with a practical use case. A legal team wants to search agreements without exposing them broadly. An engineering team wants answers from project files that contain customer designs. A support team wants to use case history while respecting customer separation. A company may also have contractual or regulatory commitments about where information can be processed.
In each case, the useful question is not simply whether the model is private. The organisation needs to know which documents can be retrieved for each employee, whether the model provider can retain inputs, where logs are stored and who can inspect them. It also needs a way to correct or remove information when the original source changes.
If the goal is to help employees find answers in company documents, our article on AI knowledge bases explains the content and search side of the problem. Private AI adds the question of how the entire data flow is governed.
Three Common Architecture Choices
1. Managed AI Service With Enterprise Controls
The simplest option for many organisations is a managed AI service that offers enterprise identity, administrative settings, contractual data protections and defined retention policies. The company may connect selected business data through approved integrations rather than building every component itself.
This can reduce setup and maintenance work, but the business still needs to understand the provider's terms and the exact data flow. It should check which regions process requests, how long prompts and outputs are retained, whether data is used to improve general models and what administrators can audit. The answer may differ by product, plan or configuration, so current documentation and agreements matter.
2. Private Knowledge Infrastructure With an External Model
In this design, the company controls the document pipeline, search index and access checks in its own environment or a dedicated tenant. When a user asks a question, the application retrieves authorised passages and sends only the material needed for that request to an external model. The model produces an answer, and the application shows the supporting sources.
This is a common pattern for enterprise retrieval-augmented generation, or RAG. It can give the business more control over indexing, permissions and source selection while avoiding the work of operating a large model. However, selected content still leaves the knowledge environment for model processing, so the provider terms, transfer controls and logging remain important.
Document-level security cannot be treated as an afterthought. Azure AI Search's access-control guidance describes approaches to enforcing permissions during retrieval. The application must also authenticate the person asking and pass the right identity context to the search layer.
3. Fully Self-Hosted or On-Premises AI
Some organisations need to keep both the knowledge system and model processing within infrastructure they control. This may be an on-premises deployment or a tightly controlled private cloud environment. It can support strong data-location requirements and allow more direct control over networking and operations.
It also brings responsibility. The organisation must operate the model, manage capacity, monitor quality, apply security updates and maintain the search and application layers. A self-hosted model can still leak information to an unauthorised employee if the application retrieves the wrong documents. Infrastructure location alone does not enforce access rights.
The right choice depends on data sensitivity, contractual obligations, expected usage, performance needs, available expertise and budget. A small pilot with well-defined information can often make these trade-offs clearer than a broad policy debate.
Follow the Data Through a Real Question
Suppose an employee asks, “What did we agree with this customer about support response times?” A private AI design should show what happens at each step. The application authenticates the employee, checks whether they may see that customer's contract, retrieves the relevant clause and sends the necessary text to the model under the chosen processing arrangement. It then returns an answer with a link to the agreement.
The team should also ask what happens afterward. Are the question, retrieved passage and generated answer logged? Who can read those logs? How long are they kept? Does the model provider retain the content? If the contract is deleted or the employee changes role, how quickly do access changes take effect in the search system?
Walking through a real question makes hidden assumptions visible. It also helps legal, security and business teams discuss the same workflow rather than using “private AI” to mean different things.
Security Controls That Matter in Every Model
Identity and permissions are the foundation. Users should sign in through the company's identity system, and retrieval should respect document, project and customer boundaries. Permission changes in the source need to propagate to the index or be checked at request time.
The system should use encryption in transit and at rest, restrict administrative access and keep useful audit records. It should define retention for uploaded files, prompts, outputs and logs. Administrators need a process for removing obsolete content and investigating an answer that cites the wrong source.
Answer quality is also a security and trust issue. The assistant should cite sources and indicate uncertainty when the documents do not support a clear answer. It should not present an inferred policy as an official one. Model behaviour, retrieval quality and source governance all affect whether an employee can rely on the result.
Questions to Ask a Private AI Provider
Before choosing a product or architecture, ask for a simple diagram of the data path. Where are source files, extracted text, embeddings, prompts, outputs and logs stored? Which organisations can access each part? Which parts cross a regional or organisational boundary?
Then ask how permissions are enforced. Does the system use the employee's existing access rights, or does it create a second permission model? How are access changes and deletions handled? Can administrators verify which source passages produced an answer?
Finally, ask about operations. What is the retention policy? What service level and recovery options apply? Who maintains connectors and model updates? How will the business test accuracy and respond to mistakes? Clear answers to these questions are more useful than a broad claim that a service is “secure by design.”
Choose Privacy Requirements Before Choosing a Tool
Start with one use case and classify the information it needs. Identify the source owner, the employee groups that should have access and any contractual or legal constraints. Then compare the three deployment approaches against those requirements, including ongoing operating costs.
A private AI solution should make company knowledge more useful while preserving the controls the business needs. Codativity can help design the data flow, search architecture and access model for a focused pilot, whether the result uses managed services, a private knowledge layer or a fully controlled deployment.
18/10/2026
Contact Us
701, Opal Tower Business Bay, Dubai United Arab Emirates
P.O.Box 126732

Let's Work Together
© 2016 - 2026 Codativity Software Solutions. All Rights Reserved.