
From PDF to Answer: How Document Ingestion, Chunking and Metadata Affect RAG Quality
Learn how source selection, extraction, chunking, metadata and refresh processes affect the quality and trustworthiness of RAG answers.
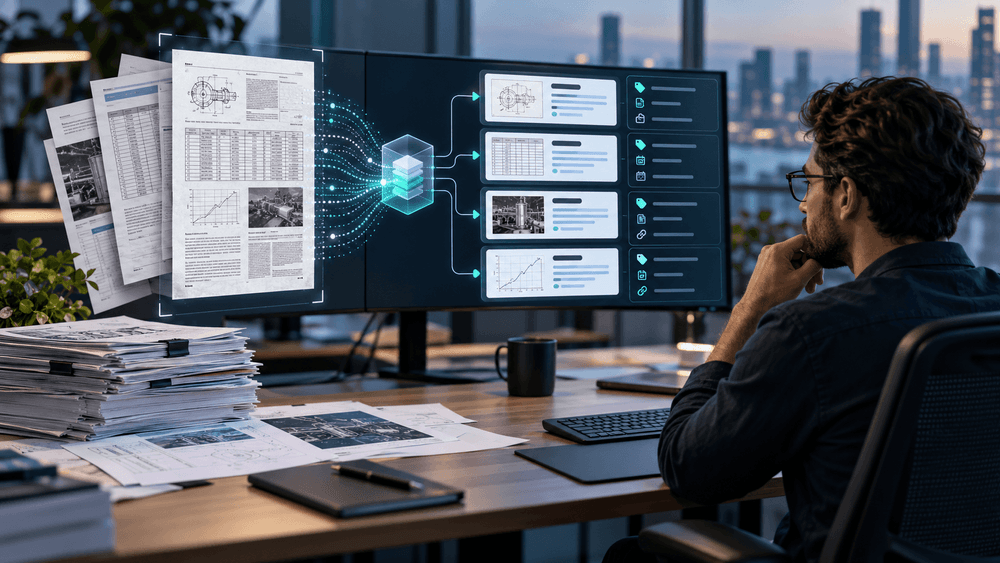
When an AI assistant gives a weak answer, the language model often gets the blame. In many cases the problem happened earlier. The right document was not ingested, a table lost its structure, a long section was split at the wrong place or the source version was missing from the search record. The model can only work with the evidence the retrieval system gives it.
Document ingestion is the process that turns files and application content into searchable material. Chunking divides that material into passages, and metadata records context such as source, project, date and access rights. These decisions determine whether an assistant can find the correct passage and show where it came from.
Start With Authoritative Sources
A company may have copies of the same procedure in SharePoint, email attachments and project folders. Indexing every copy without a rule for authority can create conflicting answers. Before ingestion, identify the system of record and how drafts, approved versions and archives are marked.
The source inventory should include file types, owners, update frequency and permissions. A technical report that changes once a year needs a different refresh process from a live operational record. The team should also identify what must be excluded: duplicate exports, personal notes or material the intended users cannot access.
This source work is part of enterprise RAG architecture, not a one-time cleanup before the “real” AI work begins.
Extract Text Without Losing Meaning
A simple text PDF may be easy to parse. A scanned document needs optical character recognition. Tables, columns, footnotes and page headers can be much harder. If extraction changes the reading order, a paragraph may be separated from its heading or a value from its unit.
The pipeline should validate what was extracted. Count unreadable pages, inspect a sample of complex files and preserve a link to the original page or section. When a document cannot be parsed reliably, the system should record the limitation rather than silently adding poor text to the index.
Some information is primarily visual, such as a construction drawing. A text-only index should not claim that it covers requirements shown only in the drawing. A more capable extraction method may be needed for that source type, followed by human checks on important examples.
Choose Chunks That Preserve Context
Search systems usually split long documents into smaller passages so they can retrieve the part relevant to a question. A very large chunk may include too much unrelated text. A very small chunk may lose the definition, exception or heading needed to understand it.
Section-aware chunking can keep related paragraphs together and carry the document title and section path into each record. Tables may need a different treatment from prose. Overlap between chunks can help preserve a boundary, but excessive overlap creates duplicates and consumes more storage and model context.
Amazon Bedrock's chunking guidance describes several strategies and the mapping back to source documents. There is no universal chunk size that fits a contract clause, a short FAQ and a long technical report equally well. The choice should be tested with the questions employees actually ask.
Metadata Makes Search Safer and More Useful
Useful metadata can include project, customer, document type, discipline, language, issue date, approval status and source URL. These fields let the application filter results and help a reader judge whether a passage applies to the current situation.
Permissions are also metadata with a security purpose. If a document is split into many chunks, those chunks need the correct access rules. A chunk must not become visible to everyone because the parser failed to carry the parent file's rights into the index.
Metadata quality varies. An old archive may have incomplete dates or inconsistent project names. A pilot can start with a controlled subset and improve the fields that matter most for its questions. Inventing missing metadata is worse than showing that it is unknown.
Refresh, Deduplicate and Remove Content
Ingestion is not finished after the first load. New files arrive, revisions replace old ones and permissions change. The pipeline needs to detect updates, retire superseded chunks and remove deleted content. Otherwise the assistant may continue citing a file that no longer represents the current process.
Duplicates can distort ranking by making one version appear more often than others. The system should recognise exact copies and identify near-duplicates for review, while preserving legitimate revisions with their status. It should also record when each source was last processed so operators can investigate a stale answer.
This operating work becomes especially important when hybrid search and reranking are added. Better retrieval algorithms cannot make an old index current.
Evaluate the Pipeline, Not Only the Final Answer
Create questions with known source passages. Check whether the correct document was ingested, whether its text is readable, whether the right chunk appears in search and whether the citation opens the expected file. Include tables, scanned pages, version changes and permission changes.
Then compare the final answer. If it is wrong, the team can see whether the failure came from extraction, chunking, retrieval or generation. Our guide to RAG evaluation explains how to separate those checks.
Good ingestion does not make AI infallible, but it gives the assistant a reliable foundation. Codativity can help build and test that foundation around your real document types, access rules and employee questions.
18/11/2026
Contact Us
701, Opal Tower Business Bay, Dubai United Arab Emirates
P.O.Box 126732

Let's Work Together
© 2016 - 2026 Codativity Software Solutions. All Rights Reserved.